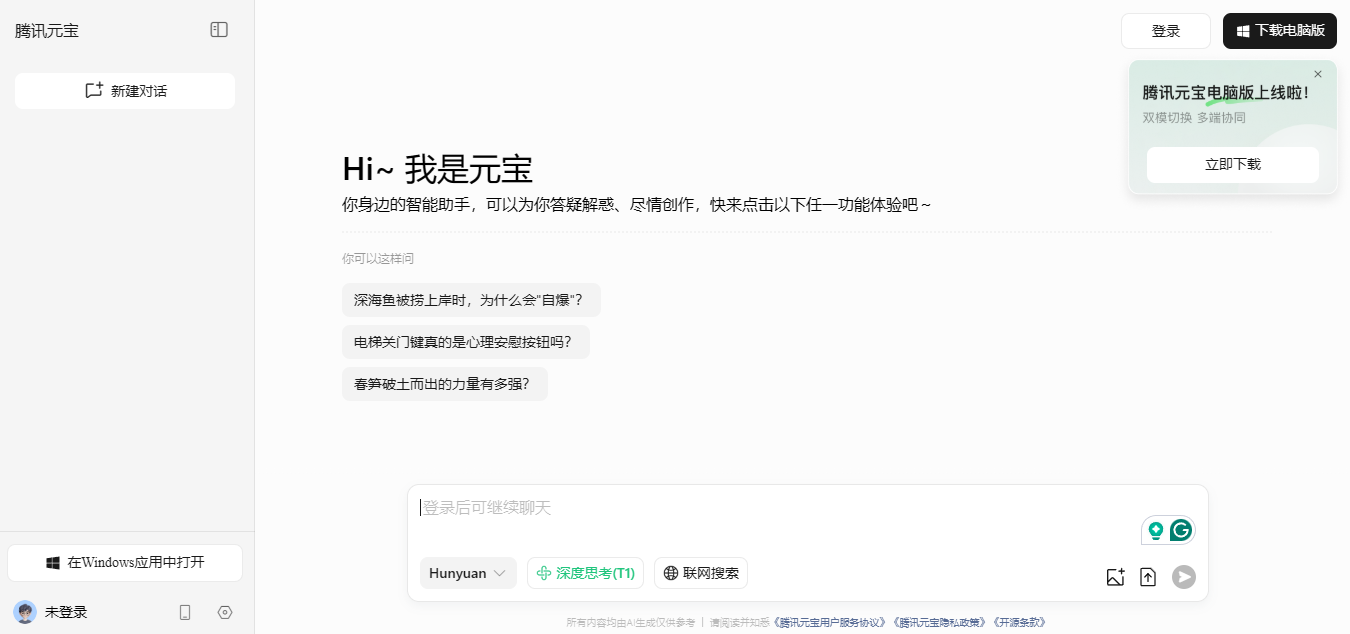
Hunyuan-TurboS
Tencent's Hunyuan-TurboS is a next-generation AI model designed to offer rapid responses and outstanding performance in various domains such as knowledge, mathematics, and creative tasks. Unlike previous models that require "slow thinking," Hunyuan-TurboS enhances response speed, doubling word output speed and reducing first-word latency by 44%. Through innovative architecture, it provides superior performance while lowering deployment costs. This model combines fast thinking (intuition-based responses) with slow thinking (logical analysis), ensuring quicker, more accurate solutions across diverse scenarios. Hunyuan-TurboS excels in benchmarks, competing with leading models like GPT-4 and DeepSeek V3, making it a breakthrough in AI-driven performance.
Learn more
HunyuanOCR
Tencent Hunyuan is a large-scale, multimodal AI model family developed by Tencent that spans text, image, video, and 3D modalities, designed for general-purpose AI tasks like content generation, visual reasoning, and business automation. Its model lineup includes variants optimized for natural language understanding, multimodal vision-language comprehension (e.g., image & video understanding), text-to-image creation, video generation, and 3D content generation. Hunyuan models leverage a mixture-of-experts architecture and other innovations (like hybrid “mamba-transformer” designs) to deliver strong performance on reasoning, long-context understanding, cross-modal tasks, and efficient inference. For example, the vision-language model Hunyuan-Vision-1.5 supports “thinking-on-image”, enabling deep multimodal understanding and reasoning on images, video frames, diagrams, or spatial data.
Learn more
Hunyuan-Vision-1.5
HunyuanVision is a cutting-edge vision-language model developed by Tencent’s Hunyuan team. It uses a mamba-transformer hybrid architecture to deliver strong performance and efficient inference in multimodal reasoning tasks. The version Hunyuan-Vision-1.5 is designed for “thinking on images,” meaning it not only understands vision+language content, but can perform deeper reasoning that involves manipulating or reflecting on image inputs, such as cropping, zooming, pointing, box drawing, or drawing on the image to acquire additional knowledge. It supports a variety of vision tasks (image + video recognition, OCR, diagram understanding), visual reasoning, and even 3D spatial comprehension, all in a unified multilingual framework. The model is built to work seamlessly across languages and tasks and is intended to be open sourced (including checkpoints, technical report, inference support) to encourage the community to experiment and adopt.
Learn more
Gemini 3.5 Pro
Gemini 3.5 Pro is Google’s anticipated next-generation Pro model in the Gemini 3.5 series, designed for advanced reasoning, coding, multimodal understanding, and agentic workflows. It is expected to build on Google’s Gemini 3 family with stronger performance for complex tasks that require planning, context handling, tool use, and deep problem solving. The model is aimed at users who need more power than faster Flash models for demanding development, research, automation, and enterprise AI use cases. Gemini 3.5 Pro is expected to support sophisticated workflows across text, code, files, multimodal inputs, and connected tools. Developers and organizations will likely use it through Google’s AI platforms for building assistants, agents, coding tools, analysis systems, and productivity applications. As an upcoming Pro-tier model, Gemini 3.5 Pro is positioned for high-value workloads where accuracy, reasoning quality, and advanced task execution matter more than maximum speed.
Learn more