
 Download

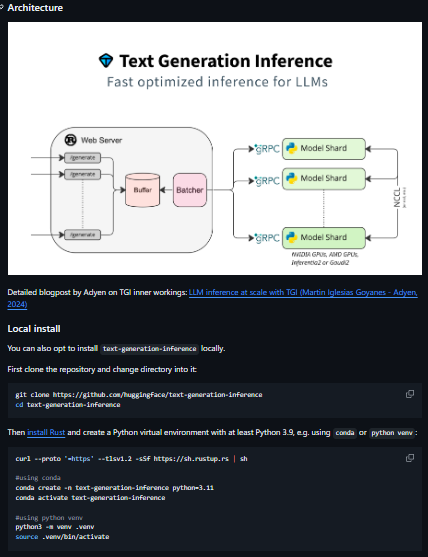
Text Generation Inference is a high-performance inference server for text generation models, optimized for Hugging Face's Transformers. It is designed to serve large language models efficiently with optimizations for performance and scalability.
Features
- Optimized for serving large language models (LLMs)
- Supports batching and parallelism for high throughput
- Quantization support for improved performance
- API-based deployment for easy integration
- GPU acceleration and multi-node scaling
- Built-in token streaming for real-time responses
Project Samples
License
Apache License V2.0Follow Text Generation Inference
Other Useful Business Software
Train ML Models With SQL You Already Know
Build and deploy ML models using familiar SQL. Automate data prep with built-in Gemini. Query 1 TB and store 10 GB free monthly.
Rate This Project
Login To Rate This Project
User Reviews
Be the first to post a review of Text Generation Inference!
